Contents
Your ML pipeline has grown from a single training script to a complex workflow — data ingestion, preprocessing, feature engineering, training, evaluation, and deployment. You’re managing dependencies with cron jobs and bash scripts held together with hope and duct tape. When something fails, you have no idea what broke or how to restart from the failure point. You know you need an orchestration tool, but everyone recommends different things.
I’ve used both Airflow and Prefect extensively for ML pipelines. Airflow at a company with 100+ data scientists, Prefect on personal projects and smaller teams. They solve the same problem — workflow orchestration — but approach it completely differently. Airflow is the established enterprise tool with every feature imaginable and all the complexity that implies. Prefect is the modern alternative that’s actually pleasant to use. Let me break down which one you actually need.
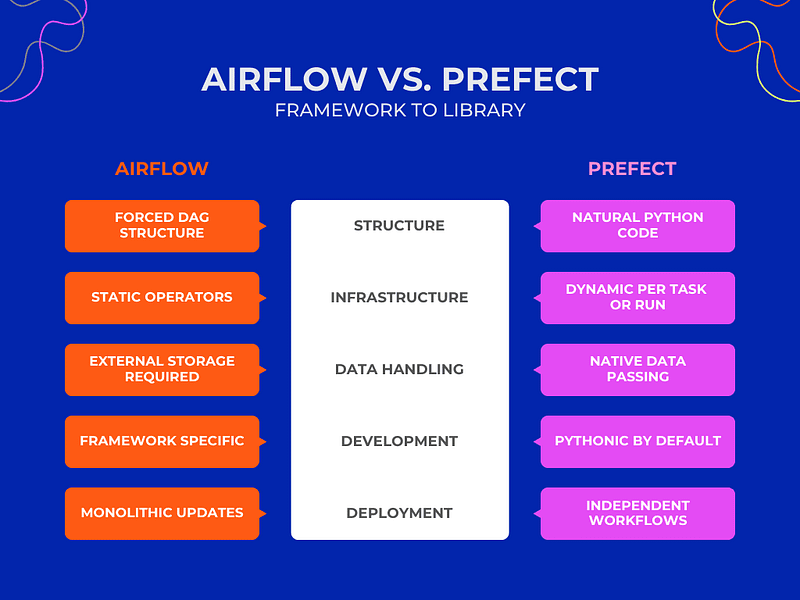
The Core Difference (Philosophy Matters)
Before comparing features, understand the fundamental philosophical difference:
Airflow (2015):
- Batch-first, scheduling-centric
- Configuration as code (DAGs in Python)
- Centralized architecture
- “Run this workflow on schedule”
Prefect (2018):
- Code-first, dataflow-centric
- Native Python, no special syntax
- Hybrid cloud architecture
- “Run this Python code as a workflow”
Airflow feels like a job scheduler with Python integration. Prefect feels like Python with orchestration capabilities. This difference permeates everything else.
Installation and Setup
Airflow Setup (Complex)
bash
# Install Airflow (specific version constraints)
AIRFLOW_VERSION=2.7.1
PYTHON_VERSION="$(python --version | cut -d " " -f 2 | cut -d "." -f 1-2)"
CONSTRAINT_URL="https://raw.githubusercontent.com/apache/airflow/constraints-${AIRFLOW_VERSION}/constraints-${PYTHON_VERSION}.txt"pip install "apache-airflow==${AIRFLOW_VERSION}" --constraint "${CONSTRAINT_URL}"# Initialize database
airflow db init
# Create user
airflow users create \
    --username admin \
    --firstname Admin \
    --lastname User \
    --role Admin \
    --email admin@example.com
# Start webserver and scheduler (separate processes)
airflow webserver --port 8080 &
airflow scheduler &
Configuration requires understanding:
- Executors (LocalExecutor, CeleryExecutor, KubernetesExecutor)
- Database backends (SQLite for dev, Postgres/MySQL for prod)
- Multiple services (webserver, scheduler, workers)
Prefect Setup (Simple)
bash
# Install Prefect
pip install prefect
# Optional: Start local server
prefect server start
# Or use Prefect Cloud (free tier)
prefect cloud login
That’s it. Prefect works locally without any setup. The server is optional for UI/monitoring.
Winner: Prefect. Setup time: 2 minutes vs. 30 minutes.
Defining Workflows
Airflow DAGs (Configuration-Heavy)
python
# airflow_dag.py
from datetime import datetime, timedelta
from airflow import DAG
from airflow.operators.python import PythonOperator
# DAG must be defined at module level
default_args = {
'owner': 'data-team',
'depends_on_past': False,
'start_date': datetime(2024, 1, 1),
'email': ['alerts@example.com'],
'email_on_failure': True,
'email_on_retry': False,
'retries': 3,
'retry_delay': timedelta(minutes=5),
}
dag = DAG(
    'ml_training_pipeline',
    default_args=default_args,
    description='ML training workflow',
    schedule_interval='0 0 * * *',  # Daily at midnight
    catchup=False
)
def load_data(**context):
    """Load data from source."""
    # Your logic here
    return data_path
def preprocess(**context):
    """Preprocess data."""
    # Get output from previous task
    data_path = context['task_instance'].xcom_pull(task_ids='load_data')
    # Your logic here
    return processed_path
def train_model(**context):
    """Train model."""
    processed_path = context['task_instance'].xcom_pull(task_ids='preprocess')
    # Your logic here
    return model_path
# Define tasks
load_task = PythonOperator(
    task_id='load_data',
    python_callable=load_data,
    dag=dag,
)
preprocess_task = PythonOperator(
    task_id='preprocess',
    python_callable=preprocess,
    dag=dag,
)
train_task = PythonOperator(
    task_id='train_model',
    python_callable=train_model,
    dag=dag,
)
# Define dependencies
load_task >> preprocess_task >> train_task
Airflow requires:
- DAG object at module level
- Special context dicts for passing data
- XComs for task communication
- Separate task definition and dependency declaration
Prefect Flows (Just Python)
python
# prefect_flow.py
from prefect import flow, task
@task(retries=3, retry_delay_seconds=300)
def load_data():
"""Load data from source."""
# Your logic here
return data_path
@task
def preprocess(data_path):
    """Preprocess data."""
    # Your logic here
    return processed_path
@task
def train_model(processed_path):
    """Train model."""
    # Your logic here
    return model_path
@flow(name="ml-training-pipeline")
def training_pipeline():
    """ML training workflow."""
    data_path = load_data()
    processed_path = preprocess(data_path)
    model_path = train_model(processed_path)
    return model_path
# Run locally
if __name__ == "__main__":
    training_pipeline()
# Or schedule (Prefect Cloud/Server)
# deployment = training_pipeline.to_deployment(
#     name="daily-training",
#     schedule={"cron": "0 0 * * *"}
# )
Prefect is just Python:
- Normal function definitions
- Standard Python argument passing
- Natural dependency from function calls
- Works locally without any infrastructure
Winner: Prefect. Prefect feels like writing Python. Airflow feels like configuring a job scheduler.
Data Passing Between Tasks
Airflow: XComs (Limited)
python
# Push data
def task1(**context):
    result = {"key": "value"}
    context['task_instance'].xcom_push(key='my_data', value=result)
# Pull data
def task2(**context):
data = context['task_instance'].xcom_pull(
task_ids='task1',
key='my_data'
)
XComs serialize data to database. Limitations:
- Size limits (typically a few MB)
- Serialization overhead
- Not type-safe
- Clunky API
Prefect: Native Python
python
@task
def task1():
    return {"key": "value"}
@task
def task2(data):
# data is the actual return value from task1
print(data["key"])
@flow
def my_flow():
    result = task1()
    task2(result)
Data flows naturally through function returns and arguments. For large data, use:
python
from prefect.filesystems import LocalFileSystem@task
def save_large_data():
# Save to filesystem/cloud storage
# Return path
return path
@task
def load_large_data(path):
    # Load from path
    return data
Winner: Prefect. Natural Python vs. database-backed serialization.
Scheduling and Triggers
Airflow Scheduling
python
# Cron-based
dag = DAG(
    'my_dag',
    schedule_interval='0 0 * * *',  # Daily
    start_date=datetime(2024, 1, 1)
)
# Complex schedules
schedule_interval='@hourly'
schedule_interval='*/15 * * * *' # Every 15 minutes
schedule_interval=timedelta(hours=6)
Airflow is scheduling-first. Everything runs on schedule.
Prefect Scheduling
python
from prefect.deployments import Deployment
from prefect.server.schemas.schedules import CronSchedule
# Cron schedule
deployment = Deployment.build_from_flow(
flow=training_pipeline,
name="daily-training",
schedule=CronSchedule(cron="0 0 * * *")
)
# Or trigger programmatically
training_pipeline()  # Run immediately
# Or from API
from prefect import flow_runs
flow_runs.create_flow_run(flow_id=flow_id)
Prefect supports:
- Scheduled runs
- Manual triggers
- Event-driven triggers
- Programmatic runs
Winner: Tie. Both handle scheduling well. Prefect’s ad-hoc execution is more flexible.
Failure Handling and Retries
Airflow Retries
python
default_args = {
    'retries': 3,
    'retry_delay': timedelta(minutes=5),
    'retry_exponential_backoff': True
}
# Task-specific
task = PythonOperator(
task_id='my_task',
python_callable=my_function,
retries=5,
retry_delay=timedelta(minutes=10)
)
Prefect Retries
python
@task(retries=3, retry_delay_seconds=[60, 120, 300])  # Exponential backoff
def my_task():
    # Task logic
    pass
# Or with custom retry logic
from prefect import task
from prefect.tasks import task_input_hash
from datetime import timedelta
@task(
    retries=3,
    retry_delay_seconds=60,
    cache_key_fn=task_input_hash,
    cache_expiration=timedelta(hours=1)
)
def expensive_computation(data):
    # Won't recompute if called with same input within 1 hour
    pass
Prefect adds caching on top of retries — smart for expensive ML operations.
Winner: Prefect. Retries plus intelligent caching.
Monitoring and Observability
Airflow UI
Pros:
- Comprehensive DAG view
- Task duration metrics
- Gantt charts
- Log viewing
- Historical runs
Cons:
- Complex interface
- Slow on large installations
- Hard to customize
Prefect UI
Pros:
- Clean, modern interface
- Real-time updates
- Flow run radar
- Simple navigation
- Customizable dashboards (Prefect Cloud)
Cons:
- Less mature than Airflow’s UI
- Fewer built-in visualizations
Winner: Tie. Airflow’s UI is feature-rich but cluttered. Prefect’s is cleaner but less comprehensive.
Deployment and Scaling
Airflow Scaling
yaml
# Kubernetes deployment (simplified)
executor: KubernetesExecutor
kubernetes:
  worker_container_repository: my-airflow-worker
  worker_container_tag: latest
  namespace: airflow
  image_pull_policy: Always
Airflow scaling is complex but powerful:
- Multiple executors (Local, Celery, Kubernetes, Dask)
- Distributed workers
- Complex but battle-tested
Prefect Scaling
python
from prefect.infrastructure import Process, DockerContainer, KubernetesJob# Run on Kubernetes
deployment = Deployment.build_from_flow(
flow=my_flow,
name="k8s-deployment",
infrastructure=KubernetesJob(
image="my-image:latest",
namespace="ml-workflows"
)
)
Prefect scaling is simpler:
- Hybrid execution model
- Agent-based workers
- Easier Kubernetes integration
Winner: Depends. Airflow for complex distributed systems. Prefect for simpler setups.
Real-World ML Pipeline Example
Airflow Version
python
from airflow import DAG
from airflow.operators.python import PythonOperator
from datetime import datetime, timedelta
def extract_data(**context):
# Extract data
return data_path
def transform_features(**context):
    data_path = context['task_instance'].xcom_pull(task_ids='extract')
    # Transform features
    return features_path
def train_model(**context):
    features_path = context['task_instance'].xcom_pull(task_ids='transform')
    # Train model
    return model_metrics
def evaluate_model(**context):
    metrics = context['task_instance'].xcom_pull(task_ids='train')
    # Evaluate
    if metrics['accuracy'] > 0.9:
        return 'deploy'
    return 'skip'
dag = DAG('ml_pipeline', default_args={...}, schedule_interval='@daily')extract = PythonOperator(task_id='extract', python_callable=extract_data, dag=dag)
transform = PythonOperator(task_id='transform', python_callable=transform_features, dag=dag)
train = PythonOperator(task_id='train', python_callable=train_model, dag=dag)
evaluate = PythonOperator(task_id='evaluate', python_callable=evaluate_model, dag=dag)
extract >> transform >> train >> evaluate
Prefect Version
python
from prefect import flow, task@task(cache_key_fn=task_input_hash, cache_expiration=timedelta(hours=6))
def extract_data():
# Extract data
return data_path
@task
def transform_features(data_path):
    # Transform features
    return features_path
@task(retries=2)
def train_model(features_path):
    # Train model
    return model_metrics
@task
def evaluate_model(metrics):
    # Evaluate
    return metrics['accuracy'] > 0.9
@task
def deploy_model(model_path):
    # Deploy if approved
    pass
@flow(name="ml-pipeline")
def ml_pipeline():
    data_path = extract_data()
    features_path = transform_features(data_path)
    model_metrics = train_model(features_path)

    if evaluate_model(model_metrics):
        deploy_model(model_metrics['model_path'])
if __name__ == "__main__":
    ml_pipeline()
Winner: Prefect. Cleaner, more Pythonic, works locally without infrastructure.
When to Choose Airflow
Use Airflow when:
- Large enterprise with existing Airflow infrastructure
- Complex, mature data engineering organization
- Need deep integration with Hadoop/Spark ecosystem
- Team comfortable with Airflow’s complexity
- 100+ DAGs in production
- Require specific Airflow providers/integrations
Airflow strengths:
- Mature ecosystem
- Extensive provider packages
- Large community
- Battle-tested at scale
- Rich UI features
When to Choose Prefect
Use Prefect when:
- Starting fresh (no existing orchestration)
- Smaller team or solo developer
- Python-first organization
- Rapid development is priority
- Modern cloud-native architecture
- Want to run workflows locally during development
Prefect strengths:
- Pythonic API
- Easier to learn
- Modern architecture
- Better local development
- Cleaner codebase
- Hybrid cloud execution
My Honest Recommendation
After using both extensively:
For new ML projects: Start with Prefect. It’s simpler, more Pythonic, and you can actually run/test workflows locally. The learning curve is gentle, and you’ll be productive immediately.
For existing Airflow shops: Stick with Airflow unless pain points are severe. Migration isn’t worth it if Airflow works for you.
For complex data engineering: Airflow’s maturity and ecosystem still edge out Prefect for very complex data pipelines with many integrations.
For ML-specific pipelines: Prefect. The code-first approach, caching, and local development align better with ML workflows.
IMO, if I were starting a new ML platform today, I’d choose Prefect without hesitation. Airflow feels like legacy infrastructure comparatively. But Airflow’s not going anywhere — it’s still the dominant player and has years of polish. The question is whether you value Prefect’s modern simplicity over Airflow’s maturity and ecosystem.
Migration and Interop
Can’t decide? Use both:
python
# Call Airflow DAG from Prefect
from prefect import task
import requests
@task
def trigger_airflow_dag():
requests.post(
"http://airflow:8080/api/v1/dags/my_dag/dagRuns",
json={"conf": {}},
auth=("user", "password")
)
# Or call Prefect flow from Airflow
from airflow.operators.python import PythonOperator
def run_prefect_flow():
    from prefect import flow_runs
    flow_runs.create_flow_run(flow_id="...")
task = PythonOperator(task_id="trigger_prefect", python_callable=run_prefect_flow)
Gradual migration or hybrid approach is possible.
The Bottom Line
Airflow and Prefect solve the same problem but appeal to different sensibilities. Airflow is the established enterprise standard with every feature and all the complexity. Prefect is the modern alternative that’s actually pleasant to use.
Choose Airflow if: You need battle-tested enterprise orchestration and can handle the complexity.
Choose Prefect if: You want modern Python-first orchestration that’s easy to learn and use.
For ML pipelines specifically, Prefect’s code-first approach, local execution, and caching make it the better choice for most teams. But Airflow’s maturity means it’s not going anywhere, and large organizations have good reasons to stick with it.
Installation:
bash
# Airflow (complex)
pip install apache-airflow
# Prefect (simple)
pip install prefect
Stop agonizing over the choice. If you’re starting fresh, try Prefect for a week. If it doesn’t click, Airflow will still be there. But you’ll probably find that Prefect’s simplicity wins. :)
Loving the article? ☕
If you’d like to help me keep writing stories like this, consider supporting me on Buy Me a Coffee: https://buymeacoffee.com/samaustin. Even a small contribution means a lot!